


No crystal ball, but a backlog: building AI products for down-to-earth Product Owners
“We really need to do something with AI.” It’s the phrase that, sooner or later, comes up for every product owner or project manager — whether from a client, a director, or a colleague. Rarely does it provide an answer to the questions that really matter: who are we building it for, what problem are we solving, and what does success look like? In her talk at Project Manager Day, Merel Markusse, a product owner at Axxes IT Consultancy and currently working at an AI start-up, demonstrated how to bring structure to projects where the end goal is still unclear. A look back at the most practical insights.
Going live is not a handover point
In a traditional software project, the process is clear: plan, build, test, go live, and then it moves into maintenance. The scope is defined in advance, the end is known, and fixing bugs makes up the bulk of the work afterwards. With AI, that process looks fundamentally different. Going live is not a finish line but a starting signal. From that moment on, you must continuously assess whether the model is still performing as expected, make adjustments via prompts, rules and fallbacks, and periodically retrain it because data and behaviour change in real-world use.
What this means in practical terms for the PM: a budget with no end date and the need to reserve ongoing capacity. A team that keeps running and does not adopt a ‘done and dusted’ attitude, as is the case with a traditional project. And a ‘definition of done’ that expands to include: monitored, with a fallback, and with a retraining plan.
The direction is no longer in your head
The second major difference is perhaps the most important and the most underestimated. With traditional software, you knew: this framework, this team, this scope – I can draw up a reasonable plan myself. With AI, that’s no longer a safe assumption. The model landscape changes every quarter, your technical team knows better than you what’s feasible today, and your competitors are experimenting with exactly the same models. Planning on your own, based solely on your own ideas, will hit a dead end before you’ve even started.
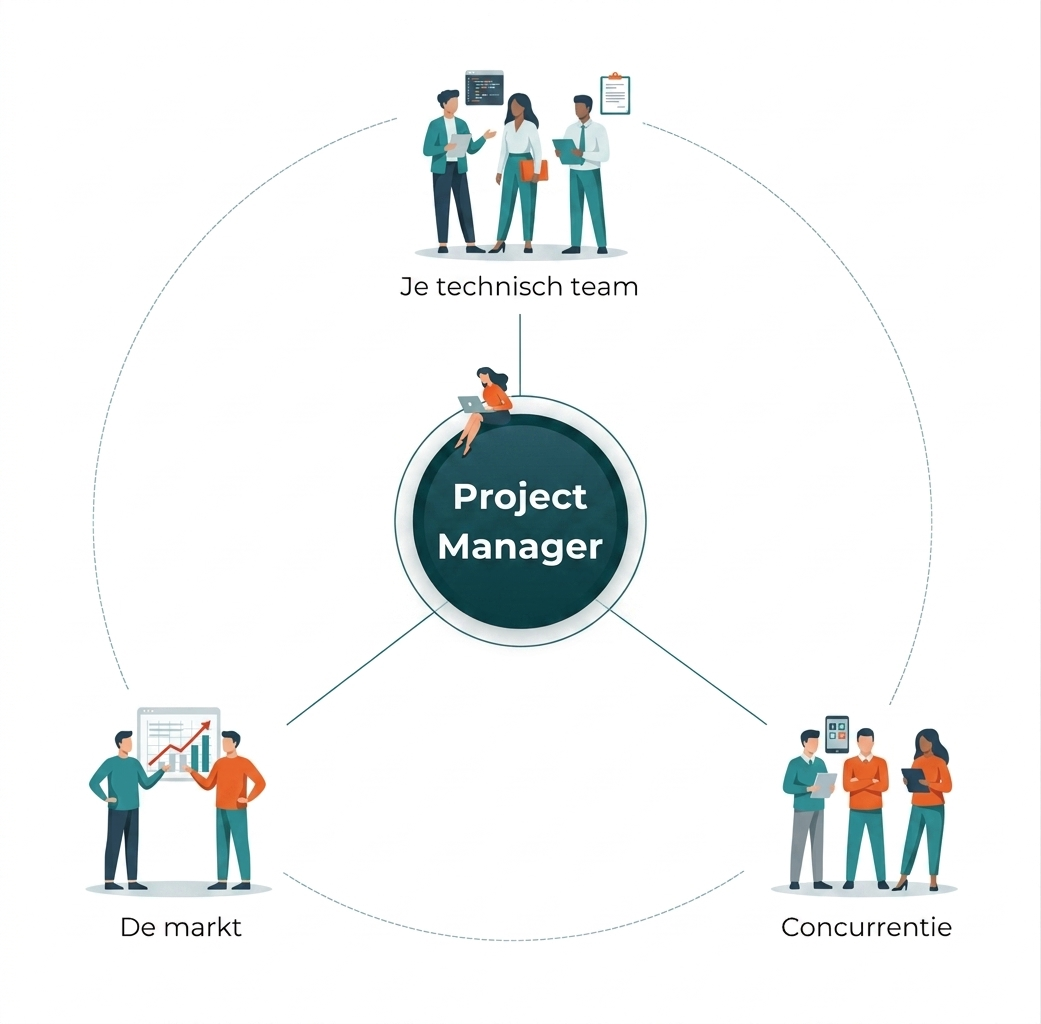
Instead, you navigate between three external realms:
- Your technical team. What can this model actually do, and what can’t it do? Ask this anew at every kick-off, because models change. Demos work better than documentation: show what the output looks like, so that everyone remains on the same page.
- The market. What’s changed this month in terms of new models, prices and APIs? What was impossible six months ago might be standard practice today. Make sure to explicitly allow room to switch, because nothing lasts forever.
- The competition. Everyone is now building with the same models, so differentiation lies elsewhere: in your unique data, workflow or context. Carry out an honest feature comparison once a quarter: where are you better, where are you lagging behind, and where are you deluding yourself?
Three practical approaches help to bring those three external worlds in without getting bogged down in them. Start the functional and technical roadmaps separately: a functional session with the business, sales and customers to discuss what we want to be able to do for whom, as well as a technical session with engineers and data specialists to discuss what is feasible using which models and what the risks are. Starting them separately prevents the functional side from becoming too conservative straight away (“that’s not technically possible”) or the technical side from becoming too ambitious (“because the business wants this”). Only in a third session do you bring them together to draw up your actual roadmap, with clear-cut choices rather than vague compromises.
In addition, set goals and KPIs at the level of outcomes, not output. Not “chatbot live in Q3”, but “60 per cent of level-1 enquiries are handled without an agent, with ≥ 80 per cent satisfaction”. For each use case: one goal, one to two KPIs, and one lower limit (“if we fall below that, we stop”). Review these every six to eight weeks; KPIs may change, but only one at a time and with justification. Also build in an ‘outside-in’ rhythm: thirty minutes each month with your tech team to discuss what’s new with the major model providers, a quarterly feature comparison with the top three competitors, and a half-yearly reality check on your choice of model.
The key message of this section: you are no longer the PM who single-handedly sets the direction and has the team carry it out. You are the PM who steers the direction between three external worlds and facilitates dialogue between them.
Start with the use case, not the feature
The sentence with which an AI project begins often predicts its success. “We want an AI chatbot” is not a problem; it’s simply a technology someone has heard about. “Account manager Sophie spends two hours every Monday preparing for her client meetings” is, however, a starting point.
The difference lies in the subject of the sentence. With feature-based thinking, the product takes centre stage and the list just keeps growing; with use-case-based thinking, a person at a specific moment takes centre stage and the list narrows down to what really helps. Only once you’ve clearly defined the use case will you even know which AI function is relevant.
A useful tool for refining this is a six-field use case canvas: who is using it, what task are they trying to perform, what is the desired outcome, what is the role of AI, what do we need to get started, and the most underestimated question: what is the biggest uncertainty? That last one tells you where your first experiment should be focused.
Four questions you always ask
Before a single AI story is written, these four questions must be addressed:
1. What problem are we solving, and for whom? Keep asking questions until you can visualise one person at a specific moment in their week, with one specific frustration. No names, no use cases.
2. What does success look like and how do we measure it? ‘Good enough’ is a number, not a feeling. Agree in advance on the minimum threshold, what you’re measuring, and what happens in cases where things go wrong.
3. What data do we have, and is it good enough? A good test: present the input a model would receive to an experienced colleague. If they say, “I can’t make a good decision with this information”, then the discussion ends. More data, or a different problem.
4. Does this actually need to be AI? Three tests help to answer that question honestly. The 80 per cent test: what solves 80 per cent of the problem without AI – an if/else statement, a form, a search function? The fit factor: can’t the rules be written down in advance; is it about patterns in large amounts of data; or does the context vary from case to case? The duct-tape test: are you using AI to try and hide something – such as poor-quality data, a vague process or unclear rules – that you should actually be resolving first?
Small, old and cheap often wins. AI is what you add where rules, forms and search functions really fall short, not where you start.
Building without a safety net: three alternatives
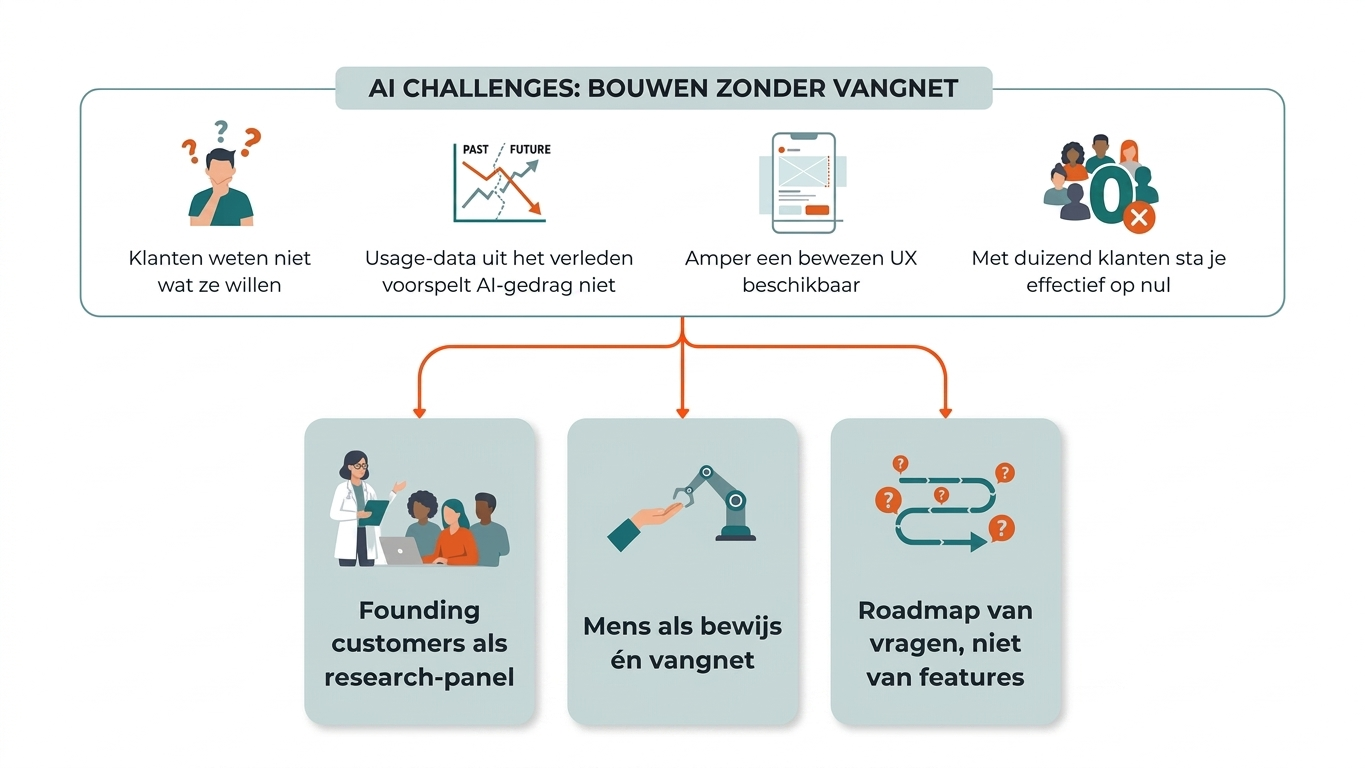
As soon as AI is incorporated into a product, three traditional safety nets disappear. Existing customers themselves do not know what they want from AI. Past usage data does not predict AI behaviour. And there is hardly any proven UX: how do you convey that ‘the model is unsure’? Even with a thousand customers, you are effectively starting from scratch. Three alternatives work in practice:
- Founding customers as a research panel. Small, engaged, honest. Don’t treat them as clients, but as co-designers; give them rough prototypes and ask what they’d criticise about them.
- People as both proof and safety net. Before development, first prove the concept manually (Wizard-of-Oz). In production, a human in the loop handles the borderline cases: above a confidence threshold, it proceeds automatically; below it, a person reviews it. In the event of failure, the system falls back gently to a human, a form or a telephone number – but not a hard crash.
- A roadmap of questions, not features. “Will we know by June whether the model is accurate enough for our data?” is a more honest goal than “feature X live in June”. The steering group is given learning objectives, not commitments.
A backlog divided into three types of work
An AI backlog consists of three types of work, deliberately categorised. Discovery removes uncertainty: hypotheses, spikes, evaluations. Capability is what the user directly experiences: traditional user stories. Reliability ensures it will still work tomorrow: drift monitoring, fallback paths, keeping costs under control. The latter is often overlooked in traditional backlogs; with AI, it is ongoing product work.
The ratio shifts in line with the phase. In the pre-product phase, your backlog is 60% Discovery and 40% Reliability, with zero Capability – that’s not an empty sprint, it’s a sprint that lays the foundations. With your first founding customers, the ratio is around 50/25/25. Once live and scaling, it shifts to 15/60/25.
Scrum involves three adjustments
Scrum isn’t a problem for AI work, provided you adapt it deliberately. One-week sprints often work better than two-week ones, because spikes last a few days and models change weekly. A sprint is no longer a delivery cycle but a decision-making cycle: at the end, you don’t necessarily deliver a feature, but an answer to a learning question. Also, take a more critical look at ceremonies: with a team of five, they can easily cost five person-days per sprint. Drop, combine or shorten anything that doesn’t add value. And divide your work across Discovery, Capability and Reliability, not just across user stories.
Three rules for stakeholders
Stakeholders haven’t changed: they want to know when something is ready, whether it works, and what benefits it brings. But with AI, these concerns are expressed differently, and misinterpreting the question leads to the wrong answer.
Show early on what failure looks like: explicitly demonstrate an incorrect answer in the first demo, so that failure is part of the product from day one rather than a bug. Express uncertainty in figures, not in words: “70–90 per cent accurate across 50 examples, go/no-go decision by the end of June” provides reassurance, whereas “it’ll be ready in June” causes panic. And stand your ground: “we’ll look into it” is a legitimate response to “if ChatGPT can do this, surely this can too?”. It’s fine to buy yourself some time, but guessing will cost you ten times as much explanation later on.
Three questions for tomorrow
Anyone who wants to take concrete action tomorrow should ask their own stakeholders three questions. What is the one user, the one moment, the one problem we are solving? What is our minimum quality standard, and what do we do with the rest? And when is the go/no-go moment, and what do we need to know then?
If you get answers to those three questions, you’ve got a project. If you don’t get answers, you know where the uncertainty lies – and that, too, is progress. Start with use cases, ask the right questions, trust your team and be honest about uncertainty. Then you’ll build AI products, even if the end picture is still a bit hazy.